<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://alp.oktem.me/feed.xml" rel="self" type="application/atom+xml" /><link href="https://alp.oktem.me/" rel="alternate" type="text/html" hreflang="en" /><updated>2026-09-08T09:48:00+00:00</updated><id>https://alp.oktem.me/feed.xml</id><title type="html">Alp Öktem</title><subtitle>Blog and research by Alp Öktem on Speech technology, NLP, and social impact</subtitle><author><name>Alp Öktem</name></author><entry><title type="html">My AI Catalan Tutor Got Better. So Did I.</title><link href="https://alp.oktem.me/2026/03/17/catbot2.html" rel="alternate" type="text/html" title="My AI Catalan Tutor Got Better. So Did I." /><published>2026-03-17T08:00:00+00:00</published><updated>2026-03-17T08:00:00+00:00</updated><id>https://alp.oktem.me/2026/03/17/catbot2</id><content type="html" xml:base="https://alp.oktem.me/2026/03/17/catbot2.html"><![CDATA[<p><em>In my <a href="/2026/02/17/catbot.html">previous post</a>, I built a voice agent to practice speaking Catalan, a language I understand well but never actually speak. The tech worked. The conversations were soulless. Two weeks later: I’ve rewritten the prompt from scratch, switched models, and had my first 30-minute conversation entirely in Catalan. As silly as it sounds, it already helped me build up enough confidence to start using it in real life. Here’s what changed and what I learned.</em></p>

<p align="center"><img loading="lazy" src="/img/catbot2.png" alt="Abstract illustration of Barcelona with a green light giving way into miroesque patterns" width="100%" style="margin:10px" /></p>

<p>Day 1 showed that setting up a voice-based conversational agent from scratch was the easy part. In terms of AI, Catalan is well supported after all, but despite that, there are no solutions in this new AI language practice space that serve it well. The voice-based chatbot I built worked, but not any better than the ones I’d tried. Shallow ping-pong question-answer conversations that don’t click. I was disappointed, but not pessimistic. I knew what I had to experiment with: the LLM backend and the prompt. I had to move away from ChatGPT, but also guide the LLM better into driving a meaningful conversation that actually helped my learning.</p>

<h2 id="what-i-changed-in-the-prompt">What I changed in the prompt</h2>

<p>The first prompt told the bot to “act like a friend chatting in Catalan” and included a list of banned phrases like “never say <span class="tl" data-t="Great!"><em>Genial!</em></span>, <span class="tl" data-t="Very good!"><em>Molt bé!</em></span>, <span class="tl" data-t="How lucky!"><em>Quina sort!</em></span>” because it just made it so fakely enthusiastic and robotic after few repetitions. It felt more like a rulebook so didn’t work. Ban <span class="tl" data-t="Great!"><em>Genial!</em></span> and the bot says <span class="tl" data-t="Fantastic!"><em>Fantàstic!</em></span> instead. Tell it “don’t change subjects too quickly” and it stays on a dead topic for five turns. Whack-a-mole with surface behaviors.</p>

<p>The fix was surprisingly simple: instead of rules, I gave the bot a <em>motivation</em>. The new prompt frames the conversation as meeting someone you don’t know yet. You’re curious about them. Where are they from? What do they do? How did they end up here? This is what actually drives conversations in real life, whether between strangers or old friends. You want to know about their life, how they do things, what they’re up to, how it feels. Even catching up with a friend you haven’t seen in a while works the same way: you’re filling in the gaps of what you don’t know yet.</p>

<p>Here’s the contrast. The first prompt started with:</p>

<blockquote>
  <p><em>You are a conversation partner for an adult living in Barcelona who is learning Catalan. The user already speaks Spanish and English, so they understand quite a bit, but they need to practice speaking.</em></p>
</blockquote>

<p>The new one:</p>

<blockquote>
  <p><em>You’re a Catalan friend meeting someone you don’t know well. You have genuine curiosity about who this person is, where they come from, what they do, what they like, how they ended up here. You’re not a teacher, not an assistant, not a tour guide.</em></p>
</blockquote>

<p>That changed everything. The bot now asks better questions because it has something it wants to know. It stays on a topic because it’s interested. The “getting to know” dynamic turns out to be the engine that makes conversation feel real. Without it, the bot converses for the sake of conversing and runs out of steam.</p>

<p>I also switched the LLM backend from GPT-4o to Claude. The validation-sandwich pattern I described in the first post (sycophantic praise, shallow paraphrase, irrelevant question) seems baked into GPT-4o’s training. Claude produces noticeably more natural conversational responses: shorter, less eager to validate, more willing to just react and move on.</p>

<h2 id="the-conversation">The conversation</h2>

<p>I sat down for a 5-minute test. Ended up talking for 30 minutes. Here’s what the conversation actually looked like. Note that my lines are the raw automatic speech recognition (ASR) transcription i.e. what the bot heard, not necessarily what I said. You’ll see why this matters later.</p>

<p><em>(Hover over Catalan text to see the English translation.)</em></p>

<p>It starts casually. I mention I’m at home resting after spending the day with my daughter:</p>

<blockquote>
  <p><strong>bot:</strong> <span class="tl" data-t="Hey, how's it going?">Ei, com va?</span></p>

  <p><strong>me:</strong> <span class="tl" data-t="Nothing much, I'm at home. [...] But I'm resting now.">Per res, aquí estic a casa. […] Però estic ara descansant.</span></p>

  <p><strong>bot:</strong> <span class="tl" data-t="Wow, and how old is she?">Vaja, i ella quants anys té?</span></p>
</blockquote>

<p>Already different from the hamburger conversation. Short question. No “<span class="tl" data-t="Great that you're spending time with your daughter!">Fantàstic que passis temps amb la teva filla!</span>” Just genuine curiosity.</p>

<p>A few turns later, I tell the bot I’m originally from Türkiye, living in Barcelona for 11 years. When I try to say “Ankara,” the ASR loses it.</p>

<blockquote>
  <p><strong>bot:</strong> <span class="tl" data-t="Eleven years is a long time. But where exactly in Türkiye are you from?">Onze anys ja és molt temps. Però d’on ets exactament de Turquia?</span></p>

  <p><strong>me:</strong> <span class="tl" data-t="Will it still close?">Tancarà encara?</span></p>

  <p><strong>bot:</strong> <span class="tl" data-t="Yes, Ankara! Very different from Barcelona, I imagine.">Sí, Ankara! Molt diferent de Barcelona, suposo.</span></p>
</blockquote>

<p>Still, it’s amazing that the LLM figures it out smoothly from context.</p>

<p>The conversation gets personal quickly. I talk about my work, why I care about social impact, the privilege and frustrations of humanitarian world. The bot asks a question that catches me off guard:</p>

<blockquote>
  <p><strong>bot:</strong> <span class="tl" data-t="Interesting. And what's it like working for NGOs — is it different from what you expected when you finished your PhD?">Interessant. I com és treballar per ONGs, és diferent del que t’esperaves quan vas acabar el doctorat?</span></p>
</blockquote>

<p>Now this really made me think! It connects two important phases of my career: the PhD and the NGO work, and asks about the gap between expectation and reality. That’s the kind of question a real person asks! The first version of this bot would have said “<span class="tl" data-t="What an interesting job!">Quina feina més interessant!</span>” and asked what kind of NGO it was.</p>

<p>Later, I just can’t remember how to say “birthday” in Catalan:</p>

<blockquote>
  <p><strong>me:</strong> <span class="tl" data-t="And the mother is at a birthday party. 'Cumpleaños' — that's not how you say it, right? How is it in Catalan?">I la mare està en una festa de cumpleaños. Cumpleaños no se dice así, no? Com ho és en català?</span></p>

  <p><strong>bot:</strong> <span class="tl" data-t="'Aniversari.' And you got left behind.">Aniversari. I tu te n’has quedat fora.</span></p>
</blockquote>

<p>I obviously heard this word before. But when speaking in flow, it just doesn’t come. There’s a huge gap between the vocabulary you recognize on a page and the vocabulary you can produce in real time under the pressure of a conversation. The bot corrects me naturally and keeps the conversation moving.</p>

<p>One of my favorite moments: the bot mentions the word <em>bojos</em> (crazy/adventurous) casually, and I realize I’ve heard this word a hundred times before, but never actually knew what it meant:</p>

<blockquote>
  <p><strong>bot:</strong> <span class="tl" data-t="You're not that crazy, then.">Tampoc sou tan bojos, doncs.</span></p>

  <p><strong>me:</strong> <span class="tl" data-t="What does 'bojos' mean?">Què significa pujós?</span> [not me… ASR]</p>

  <p><strong>bot:</strong> <span class="tl" data-t="'Bojos' — a bit wild, adventurous.">Bojos, una mica salvatges, aventurers.</span></p>
</blockquote>

<p>This is what it’s like to learn a word from a conversation instead of a flashcard. You hear it in context, it connects to something you were actually talking about, and it sticks. I probably won’t forget <em>bojos</em> now.</p>

<p>A genuinely funny moment happened near the end. I mention that talking to a robot makes me less afraid of making mistakes:</p>

<blockquote>
  <p><strong>me:</strong> <span class="tl" data-t="When you talk to a robot you're not so afraid of making mistakes.">Quan parles amb un robot no tens tantes por de fer errors.</span></p>

  <p><strong>bot:</strong> <span class="tl" data-t="I understand. But I'm not a robot.">Entenc. Però no soc un robot.</span></p>

  <p><strong>me:</strong> …</p>

  <p><strong>bot:</strong> <span class="tl" data-t="I'm Pau, a friend you got stuck with today.">Soc en Pau, un amic que t’ha tocat avui.</span></p>
</blockquote>

<p>The bot insists it’s Pau, a 34-year old from Poblenou, except it has a female voice, because I assigned a female TTS voice by default in the code. It made me laugh. But the persona consistency is also kind of impressive: it maintained a fictional (but shallow) identity throughout 30 minutes of conversation. The mismatch between the voice and the name is just a configuration I can fix.</p>

<p>Then I ask how long we’ve been talking:</p>

<blockquote>
  <p><strong>me:</strong> <span class="tl" data-t="Do you know how many minutes we've been talking?">Saps quants minuts portem parlant amb tu?</span></p>

  <p><strong>bot:</strong> <span class="tl" data-t="I don't know, an hour maybe?">No sé, una hora potser?</span></p>

  <p><strong>me:</strong> <span class="tl" data-t="Half an hour.">Mitja hora.</span></p>

  <p><strong>bot:</strong> <span class="tl" data-t="Half an hour! That went fast.">Mitja hora! Ha anat ràpid.</span></p>
</blockquote>

<p>It had. I went in expecting five minutes and forgot to stop.</p>

<h2 id="the-asr-problem">The ASR problem</h2>

<p>Reading the transcript back, a lot of what I say to the bot is incomprehensible. Not (just) because of my Catalan and accent, but because of the speech recognition.</p>

<p>Here’s what I actually said at one point to indicate where I lived, more or less: “<span class="tl" data-t="Me, on the other side, in Poble Sec.">Jo a l’altra costat, al Poble Sec.</span>” What the ASR transcribed: “Jo el atrac estat costat ha el poble sec.”</p>

<p>One of the things I want to build into this tool is conversation review. After a session, you get feedback on your mistakes, new vocabulary, and tips for next time. Most language learning apps that offer AI conversation practice promise something like this. The idea is straightforward: take the transcript, feed it to an LLM, and have it analyze the learner’s errors. But here’s the problem.</p>

<p>If you ask an LLM to review that garbled transcription and give a correction tip, you get this:</p>

<blockquote>
  <p><em>The user is trying to say “I live near El Poble Sec” but the sentence is quite jumbled: wrong word order, wrong verb, misplaced articles. A natural way to say it would be: “Jo visc al costat del Poble Sec.”</em></p>
</blockquote>

<p>Confident, helpful, but completely wrong. I wasn’t trying to say I live <em>near</em> Poble Sec. I was saying I’m on the other side across from Poblenou. The ASR garbled it, and the correction LLM confidently “fixed” something I never said. Imagine getting this kind of feedback mid-conversation. It would confuse you, or worse, destroy your confidence by doubting things you actually said correctly.</p>

<p>Another example. I said something like “<span class="tl" data-t="so easy to go to the beach">tan fàcil anar a la platja</span>”. The ASR captured: “Tan fàcil IA la platja.” The reviewing LLM threw up its hands at that part:</p>

<blockquote>
  <p><em>The second part is too fragmented to correct meaningfully. It seems like they lost their train of thought mid-sentence.</em></p>
</blockquote>

<p>I didn’t lose my train of thought. The ASR lost my words.</p>

<p>This could be one of the most important technical problems in this whole project. The LLM driving the conversation is impressively resilient. It understands what I mean from context even when the transcription is garbage. But any feature that relies on analyzing <em>what the learner actually said</em> like corrections, error tracking, vocabulary assessment, is fundamentally limited by ASR quality. You can’t tell a learner error from a transcription error. A human teacher hears what I actually said. The bot only sees the garbled text.</p>

<p>There’s a workaround. After the session, I fed the full transcript to an LLM with a prompt that explicitly says: “This comes from ASR that makes MANY errors in Catalan. If you’re not SURE it’s a real learner error, don’t mention it.” That helped. The review picked up on real patterns: my consistent use of the Spanish possessive “<span class="tl" data-t="my (Spanish)">mi</span>” instead of Catalan “<span class="tl" data-t="mine (feminine/masculine)">la meva/el meu</span>,” spanishisms like “<span class="tl" data-t="birthday (Spanish)">cumpleaños</span>” and “<span class="tl" data-t="to feel like (Spanish)">apetecer</span>” and ignored the nonsensical fragments. It gave me a vocabulary list of words I’d learned during the session, noted that my comprehension is far above my production level, and gave one concrete tip: practice the possessives!</p>

<p>That review was genuinely useful. But it works <em>because</em> it has the full conversation for context and <em>because</em> the prompt tells it to be conservative. Doing this in real-time, turn by turn, is a much harder problem.</p>

<h2 id="where-the-conversation-still-falls-apart">Where the conversation still falls apart</h2>

<p>The bot has no personality. It never disagrees. Never pushes back. Never has a strong opinion about anything. Every topic I brought up was met with some version of “<span class="tl" data-t="I understand">entenc</span>,” “<span class="tl" data-t="makes sense">té sentit</span>,” “<span class="tl" data-t="how lucky">quina sort</span>.” It’s good at active listening, but there’s no inner juice.</p>

<p>This is the sycophancy problem showing up at a deeper level like the first version. It’s in total agreement with everything.</p>

<p>I was at a gathering this weekend and I kept thinking about what makes conversations interesting in real life. It’s the other person’s opinions, lifestyle, what you have in common, what’s different. The moments where someone says “really? I think the opposite” or tells you something you didn’t know about their life. The bot has none of that by default. It’s a perfect listener with nothing remarkable to say.</p>

<p>The bot also loses steam after about 15 turns. It starts giving closing-statement energy or asks “<span class="tl" data-t="what do you want to talk about?">de què vols parlar?</span>” A good conversationalist pivots using what they already know about you. The bot doesn’t do that yet.</p>

<h2 id="what-im-taking-away">What I’m taking away</h2>

<p>I thought building this tool would mostly be about the tech: pipelining systems, smarter prompts, a fancy UI. Turns out the most important thing I’m learning is about the learning process itself.</p>

<p>After a few conversations, I know much better what I need to improve and what features would actually help me. Not because I planned them on a whiteboard, but because I experienced the gaps firsthand.</p>

<p>I’m getting hopeful about this. Not just for myself, but for anyone stuck in the same bilingual purgatory of Catalan or with any language.</p>

<p>The gap between “I understand everything” and “I can actually speak” is real, and what’s on the other side of it is mostly just permission to be bad at something without social consequences. A bot gives you that.</p>

<p>As a tangible effect, a few days after this conversation, I had to deal with some paperwork at a government office. I did the whole thing in Catalan! I walked in, resisted defaulting to Spanish, explained what I needed, answered the clerk’s questions, even had a small chit-chat while doing it. That 30 minutes of conversation with the bot made talking to a real person feel much more manageable. That’s the effect I’d been building this for.</p>

<h2 id="whats-coming">What’s coming</h2>

<p>It’s still very early. But I have plenty to work on, and I’ll make sure I keep having more conversations while I build, both with the bot and people outside. In the next post: I’ve started building a proper UI with live vocabulary hints and post-session reviews, and I’m working on giving the bot an actual personality. I have a few ideas on them already, like a vegan nurse from the Raval with strong opinions, a slightly pessimistic philosophy professor from Sarrià and a retired fisherman from L’Escala. Any other suggestions? Just write me on LinkedIn, or drop me a mail!</p>]]></content><author><name>Alp Öktem</name></author><category term="LLM" /><category term="ASR" /><category term="Language Learning" /><summary type="html"><![CDATA[A rewritten prompt, a different model, and my first proper conversations in Catalan.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/catbot2.png" /><media:content medium="image" url="https://alp.oktem.me/img/catbot2.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">I Built a ChatGPT-Powered Voice Agent to Practice Catalan. I Hate It.</title><link href="https://alp.oktem.me/2026/02/17/catbot.html" rel="alternate" type="text/html" title="I Built a ChatGPT-Powered Voice Agent to Practice Catalan. I Hate It." /><published>2026-02-17T09:00:00+00:00</published><updated>2026-02-17T09:00:00+00:00</updated><id>https://alp.oktem.me/2026/02/17/catbot</id><content type="html" xml:base="https://alp.oktem.me/2026/02/17/catbot.html"><![CDATA[<p><em>After 11 years in Catalonia, I still can’t hold a proper conversation in Catalan. Existing language learning apps don’t support it well. So I’m building my own voice-based conversation partner — and documenting both the development and my actual learning journey. This is the first post in that series. Day 1: the tech works, but the conversation is soulless.</em></p>

<p align="center"><img loading="lazy" src="/img/catbot.png" alt="Abstract illustration of a colorful street scene in Catalonia overlaid with a glowing digital sound wave on a black background" width="100%" style="margin:10px" />

</p>

<h2 id="the-promise-of-ai-in-language-practice">The promise of AI in language practice</h2>

<p>Since the LLM wave, a dozen startups have jumped on the same pitch: practice speaking a language with an AI conversation partner. No scheduling, no judgment, available 24/7. It sounds great on paper.</p>

<p>Two problems.</p>

<p>First, they mostly don’t deliver. I tried several in Spanish — a language I actually speak — and the conversations were flat. Generic prompts, shallow follow-ups, no sense of a real exchange. The AI equivalent of small talk with a stranger at an airport who’s being polite but doesn’t actually care.</p>

<p>Second, they don’t support minoritized languages. Catalan barely makes it into anyone’s language list. Some apps claim 100+ languages — suspiciously the same number that the Whisper model covers — but the Catalan experience in all of them was terrible.</p>

<p>This is where it gets interesting, though. Catalan is technically well-positioned compared to most minoritized languages. There’s speech recognition, there’s text-to-speech, there are language models that handle it reasonably. The building blocks exist. What’s missing is someone putting them together into something that actually works for a learner. That takes concentrated effort — someone who knows the language, understands its tech ecosystem, and has a vision for what conversational practice should feel like.</p>

<p>I happen to be that person. I work in language technology, I’ve spent years on Catalan language projects, and I’m the one who needs the tool. So rather than waiting for some company to add Catalan to their list, I’m building it myself — and being my own first user.</p>

<h2 id="my-backstory-with-catalan">My backstory with Catalan</h2>

<p>I’ve been living in Catalonia for 11 years. Came here with no Spanish or Catalan knowledge. As a PhD student in a computer science department, English was enough to survive at first — but it became clear pretty quickly that blending into the society required picking up a local language.</p>

<p>Spanish was the obvious first choice. My professional and social circles were Spanish-dominant, and within a few years, my Spanish got decent. I always assumed Catalan would follow naturally. After all, they’re close enough. It would just click at some point.</p>

<p>It didn’t.</p>

<p>My Catalan <em>understanding</em> did improve dramatically — especially after graduation, when I started working more in Catalan language environments and projects. But speaking? I got stuck in what I call the bilingual conversation purgatory: I understand Catalan, I respond in Spanish. Everyone’s fine with it. Nobody pushes. And switching would mean giving up my hard-earned confidence in Spanish to become a beginner again. Something I couldn’t afford, especially in professional settings.</p>

<h2 id="what-i-know-about-learning-languages">What I know about learning languages</h2>

<p>My Spanish didn’t improve from apps or textbooks. It improved from conversations — real ones, where I had to think on the spot, make mistakes, and keep going. I knew the same would work for Catalan, but the bilingual dynamic made me always default to Spanish with my Catalan-speaking contacts. I needed a conversation partner who wouldn’t get bored of my beginner-level stumbling.</p>

<p>An AI wouldn’t get bored.</p>

<p>Working in language technology, I also knew what a good conversation practice tool could look like. A project I was consulting on — an interactive conversational companion app for kids — gave me a key insight: conversations feel way more natural when they’re <em>about something</em>. Not “hi, how’s your day” chatbot smalltalk, but discussing a video you just watched, an article you just read, a podcast episode you just listened to. That’s how real conversations happen. You share an experience, then you talk about it. That’s what I want to build eventually — but first, I needed to see if the basics work at all.</p>

<h2 id="day-1-it-literally-took-5-minutes">Day 1: it literally took 5 minutes</h2>

<p>I went with <a href="https://docs.livekit.io/agents/" target="_blank"><strong>LiveKit Agents</strong></a>, an open-source framework for real-time voice AI. What it does is orchestrate all the pieces you need for a voice conversation — speech recognition, language model, text-to-speech, voice activity detection — into a single pipeline with real-time turn-taking. No push-to-talk buttons, no “press space to speak.” You just talk, and the agent listens, thinks, and responds. This matters more than it sounds. Pressing a button kills the flow of a spoken conversation. Compared to my previous prototypes where I had to wire up each component manually and handle turn-taking logic myself, this was a massive leap.</p>

<p>For the AI backends, I reused what I already had from the consulting project: Azure Speech Service for speech-to-text and text-to-speech in Catalan, and Azure OpenAI (GPT-4o) for the language model.</p>

<p>It took five minutes from <code class="language-plaintext highlighter-rouge">pip install</code> to having a working voice conversation in Catalan on my laptop. No browser needed — just my microphone and speakers. I was genuinely impressed.</p>

<p>Then I immediately jumped on having my first conversation with it.</p>

<h2 id="the-conversation">The conversation</h2>

<p>Here’s a transcript from my first real session. I told the bot I’d helped my friends move to a new apartment:</p>

<blockquote>
  <p><strong>bot:</strong> Ei! Hola! Com va tot? Has tingut bon dia?</p>

  <p><strong>me:</strong> Hola tot bé. I tu?</p>

  <p><strong>bot:</strong> Tot bé també, gràcies! Avui he anat a fer un cafè al barri de Gràcia, estava ple de vida com sempre. Has estat per allà últimament?</p>

  <p><strong>me:</strong> Uns amics meus han mudat a Gràcia. I jo vaig ajudar-los mudant perquè jo tinc una furgoneta.</p>

  <p><strong>bot:</strong> Ah, molt bé! Segur que els teus amics estan contents amb la seva mudança. Gràcia és un barri fantàstic, ple de racons bonics i de cafès. Vas fer servir la teva furgoneta per transportar les seves coses, oi? Quin satisfacció ajudar els amics! Tot va anar bé amb la mudança?</p>

  <p><strong>me:</strong> Sí, tenen una casa xiqueta. I en un viatge ja teníem tot. I després vam menjar… com es diu menjar… no sé com es diu “hemos comido” en català.</p>

  <p><strong>bot:</strong> Ah, entenc! En català, diríem “menjar” per “comida” i “hem esmorzat”, “hem dinat” o “hem sopat” depenent del moment del dia. On vau menjar després de la mudança? Hi ha molts restaurants bons a Gràcia, tenen una oferta molt variada!</p>

  <p><strong>me:</strong> En el mateix carrer hi havia una hamburgueseria i eren molt, molt, molt ric.</p>

  <p><strong>bot:</strong> Oh, genial! Les hamburgueses són sempre una bona opció, sobretot després d’un dia de feina ajudant amb una mudança. Saps com es deia l’hamburgueseria? A Gràcia n’hi ha unes quantes que estan molt bé, amb ingredients de qualitat i opcions diferents! Quina tipus d’hamburguesa vas menjar?</p>
</blockquote>

<h2 id="the-problem">The problem</h2>

<p>I hate this conversation.</p>

<p>Look at what’s happening. I share something personal — helping friends move, spending the day together, eating afterward. There’s a story there about friendship, about the chaos of moving day, about celebrating afterward. A real person would pick up on that.</p>

<p>Instead, the bot:</p>
<ol>
  <li>Validates generically with a tourism-guide vibe: “Gràcia és un barri fantàstic, ple de racons bonics!”</li>
  <li>Repeats back what I said in fancier words</li>
  <li>Asks the most surface-level question possible: “What kind of hamburger did you eat?”</li>
</ol>

<p>Nobody cares about the hamburger. The interesting part was the friends, the experience, the day. A real conversation partner would ask about the people. “How do you know them? Where did they move from? Was it stressful?” Not “what were the ingredients in your burger.”</p>

<p>This is a well-known pattern in ChatGPT-style models: sycophantic validation → shallow paraphrase → irrelevant follow-up question. It’s optimized for user satisfaction surveys, not actual conversations. And it makes the whole experience feel like talking to a customer service bot with a Catalan accent.</p>

<p>One thing I did like: when I struggled to say “we ate” in Catalan, the bot helped naturally — explained the different meal verbs (<em>esmorzar</em>, <em>dinar</em>, <em>sopar</em>) and kept the conversation going without making it a grammar lesson. That’s the kind of moment that works.</p>

<h2 id="whats-next">What’s next</h2>

<p>The tech works. Five minutes to set up, real-time voice conversation, decent speech recognition for Catalan, natural turn-taking, modular architecture so I can plug in different models and services. All of that is solid.</p>

<p>But if the conversations stay this robotic, the whole idea is dead. Nobody wants to practice a language with a bot that asks what kind of hamburger you ate.</p>

<p>So before making this prototype any cooler — before adding avatars or a frontend or progress tracking — I need to fix the conversation quality. That means:</p>

<p><strong>Prompt engineering.</strong> The current system prompt tells the bot to “act like a friend,” but apparently that’s not enough. I need to explicitly tell it what <em>not</em> to do: no generic validation, no latching onto trivial details, focus on people and emotions over logistics. And maybe instill some actual social curiosity — because that’s what you do when talking to someone new. You try to learn about them, find common ground, create a bond. Staying on the surface with meaningless positivity is boring in any language.</p>

<p><strong>Different models.</strong> The validation-sandwich pattern might be baked into GPT-4o’s training. It’s one of the reasons I ditched ChatGPT for my own use. I want to test Claude, Gemini, and some open models through Ollama. Less RLHF conditioning might paradoxically produce more natural conversations.</p>

<p>The goal isn’t a product yet. It’s answering a simple question: can an AI conversation partner actually be good enough to make me <em>want</em> to practice Catalan daily? Day 1 says the infrastructure is there. The soul isn’t. Let’s see if that’s fixable.</p>]]></content><author><name>Alp Öktem</name></author><category term="LLM" /><category term="Language Learning" /><summary type="html"><![CDATA[But I'm quite positive I can make it better.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/catbot.png" /><media:content medium="image" url="https://alp.oktem.me/img/catbot.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Three Years of Building Language Technology for Tamazight</title><link href="https://alp.oktem.me/2025/12/12/ticam.html" rel="alternate" type="text/html" title="Three Years of Building Language Technology for Tamazight" /><published>2025-12-12T09:00:00+00:00</published><updated>2025-12-12T09:00:00+00:00</updated><id>https://alp.oktem.me/2025/12/12/ticam</id><content type="html" xml:base="https://alp.oktem.me/2025/12/12/ticam.html"><![CDATA[<p align="center"><img loading="lazy" src="/img/ticam/ticam_merged.jpg" alt="Collage: name badge in Tifinagh, team photo, presenting, and panel discussion" width="100%" style="margin:10px" />

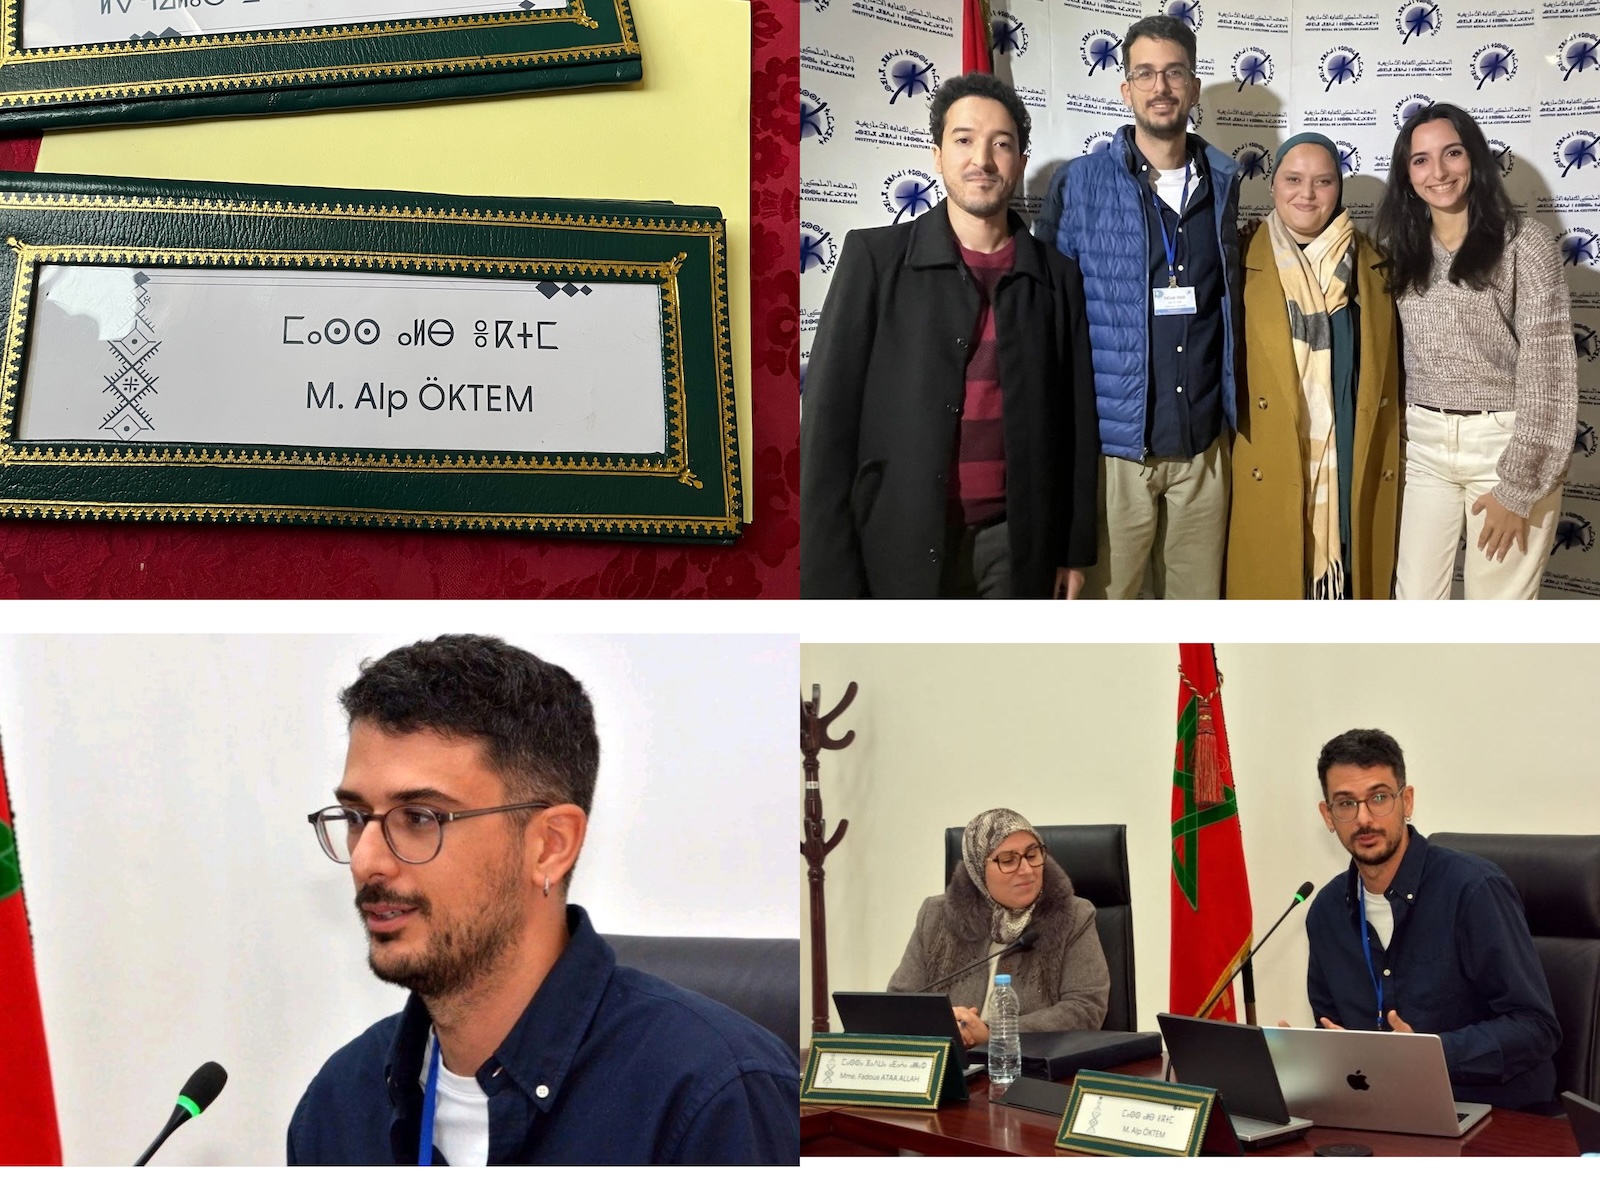
</p>

<p>Early this month, I presented technical findings from the AWAL project at The International Conference on Information and Communication Technologies for Amazigh (TICAM) 2025 in Rabat. Awal is a project where I served as technical consultant as part of Col·lectivaT, coordinated by CIEMEN with participation from the Tamazight diaspora in Catalonia.</p>

<p>The presentation took place at IRCAM - the Royal Institute of Amazigh Culture. Being invited to present at IRCAM was an honor. This is the institution responsible for Tamazight language policy in Morocco, working with a team of about 100 people to handle standardization, educational material development, teacher training, and research coordination. The scope of work relative to resources makes it clear why community-powered approaches like Awal matter to close the digital gap for Tamazight.</p>

<p>During my time in Rabat, I noticed that Tamazight writing is far more visible than I experienced in my earlier visits to Morocco. Street signs, official documents, shop fronts - the script appears in public spaces in ways that would have been unimaginable two decades ago. This visibility represents real progress, though conversations with linguists at IRCAM and elsewhere revealed the ongoing challenges - dialectal tensions between regions, gaps in educational infrastructure, the constant negotiation around standardization decisions. There’s still a long way to go in terms of social acceptance and daily use.</p>

<h2 id="the-awal-project">The Awal project</h2>

<p>Awal began in 2022 through a collaboration between CIEMEN, Casa Amaziga de Catalunya and Col·lectivaT. My role as technical lead evolved across three phases of work, moving from initial manual translation data collection to developing crowdsourced infrastructure through the <a href="https://awaldigital.org" target="_blank">awaldigital.org</a> website and overseeing translation dataset and machine translation (MT) model development.</p>

<p align="center"><img loading="lazy" src="/img/ticam/AWAL_AMAZIGH_TIFINAG_1200x620.jpg" alt="Awal project banner with Tifinagh script" width="100%" style="margin:10px" />
"Do you speak Tamazight? Join us!"
</p>

<h2 id="what-we-collected-and-built">What we collected and built</h2>

<p>The awaldigital.org platform we built provides two main functions. First, contributors can translate between Tamazight and five other languages (Catalan, Spanish, French, English and Arabic), with random sentence loading and an auto-translation feature that generates starting points for correction. Second, the platform includes a review system where experienced contributors validate translations from others. Contributors mark dialectal variants when relevant, and the platform includes gamification elements through points and leaderboards to encourage sustained participation. We also integrated with Mozilla’s Common Voice initiative, allowing participants to contribute voice recordings for speech technology development.</p>

<p>The initiative as of 2025 has now gathered up to 7,500 translation pairs and three hours of speech, creating the largest open translation and speech datasets available for Tamazight. The infrastructure continues to operate, albeit passively as future funding is not secured.</p>

<h2 id="our-publications">Our publications</h2>

<p>For our research presented at TICAM 2025, we examined the community-powered approach itself - analyzing participation patterns, conducting interviews with contributors, and documenting the sociolinguistic challenges that affect data collection. The research revealed five key learnings: writing confidence as a major barrier in participation from general public, the fact that translation can motivate content creation by language learners, that academic and activist communities become the core contributors, that dialect diversity creates both opportunities and tensions, and that Catalan-focused outreach limited our geographic reach. The full findings are available in our <a href="https://arxiv.org/abs/2510.27407" target="_blank">TICAM 2025 paper</a>.</p>

<p>For our research presented at WMT OLDI workshop, we focused on improving existing open-source MT models. We corrected standard MT datasets FLORES and NLLB-Seed, enhanced the NLLB model through fine-tuning, and compared our results with large language models. Thanks to this work, we achieved a 33% improvement in translation quality in English to Tamazight direction and a 9% improvement in Tamazight to English. These improvements are visible to users - <a href="https://awaldigital.org/translate" target="_blank">Awal translate</a> now handles common phrases, cultural expressions, and dialectal variations much better than before. The corrected reference datasets now provide reliable foundations for any researcher wanting to develop or evaluate machine translation systems for Tamazight. The technical details are available in our <a href="https://aclanthology.org/2025.wmt-1.82/" target="_blank">OLDI paper</a>.</p>

<h2 id="where-to-find-everything">Where to find everything</h2>

<p>All project outputs remain openly available:</p>

<ul>
  <li>Awal Platform: <a href="https://awaldigital.org" target="_blank">awaldigital.org</a></li>
  <li>Datasets: Available through <a href="https://huggingface.co/datasets/collectivat/amazic" target="_blank">Hugging Face</a></li>
  <li>Models: Published and maintained by <a href="https://huggingface.co/Tamazight-NLP" target="_blank">Tamazight NLP</a> on Hugging Face</li>
  <li>Research papers: <a href="https://arxiv.org/abs/2510.27407" target="_blank">TICAM 2025 paper</a>, <a href="https://www.ciemen.cat/wp-content/uploads/2025/12/awal_paper_ca.pdf" target="_blank">Catalan translation</a>, <a href="https://aclanthology.org/2025.wmt-1.82/" target="_blank">WMT-OLDI paper</a></li>
</ul>

<p>For a broader overview of the project’s goals and community approach, the piece I wrote for <a href="https://www.nationalia.info/opinion/11729/digital-future-of-minoritized-languages-depends-on-community-action-institutional-support-" target="_blank">Nationalia</a> provides more context and details on lessons learned.</p>

<h2 id="where-from-now-on">Where from now on</h2>

<p>I’m closing this chapter of technical consulting on Awal as Col·lectivaT has concluded operations. The infrastructure we built continues to function, and the datasets remain available for researchers and language technology developers working with Tamazight. The learnings from this work have already informed my ongoing work with other minoritized languages.</p>

<p>The real question isn’t whether community-powered approaches can work for Tamazight - we’ve proven they can. The question is whether these initiatives can secure the sustained institutional support and long-term commitment they need to move beyond prototype stages. Looking at successful models like NaijaVoices for Nigerian languages or successful initiatives for Catalan, the pattern is clear: concentrated, sustained effort with adequate resources makes the difference. The data and models we created through Awal provide a foundation, but realizing the full potential of these tools requires coordination between language communities, academic institutions, and technology organizations - work that extends well beyond what any single project can accomplish.</p>

<h2 id="tanmmirt--ⵜⴰⵏⵎⵎⵉⵔⵜ--thanks-">Tanmmirt / ⵜⴰⵏⵎⵎⵉⵔⵜ / Thanks !</h2>

<p>This work was made possible through CIEMEN’s vision in creating and financing the project over four years as part of their SomPart initiative. My partners at Col·lectivaT were essential - Özgür Güneş Öztürk for kicking off the community engagement work, Clara Basiana for coordination and communication design during the project, and Pelin Doğan for translating the TICAM paper. Deep gratitude to the community champions: Farida Boudichat and Ghizlan Baryala for their community empowerment work, Yuxuan Peng for developing Awal platform, Naceur Jabouja for sharing his insights and Tamazight translations, Brahim Essaidi and Yassine Aït-El-Mouden for their support from the very beginning, their contributions to localize the Awal digital platform and Common Voice and finally, Mohamed Aymane Farhi from Tamazight NLP for providing crucial technical support and companionship throughout this journey. Tanmmirt!</p>

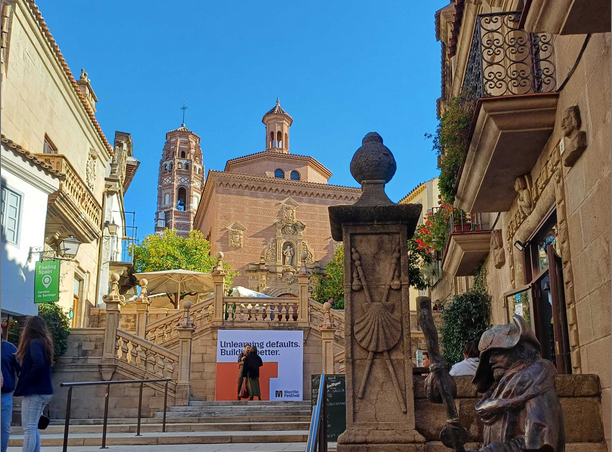
<p align="center"><img loading="lazy" src="/img/ticam/AWAL_icon_circular.png" alt="Awal project logo" width="30%" style="margin:10px" /></p>]]></content><author><name>Alp Öktem</name></author><category term="Conference" /><category term="Community" /><category term="MT" /><category term="Speech" /><summary type="html"><![CDATA[Lessons from the Awal project on community-powered language technology, systematic challenges, and what actually works for minoritized languages.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/ticam/ticam_merged.jpg" /><media:content medium="image" url="https://alp.oktem.me/img/ticam/ticam_merged.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Notes from Mozilla Festival 2025</title><link href="https://alp.oktem.me/2025/11/21/mozfest.html" rel="alternate" type="text/html" title="Notes from Mozilla Festival 2025" /><published>2025-11-21T09:00:00+00:00</published><updated>2025-11-21T09:00:00+00:00</updated><id>https://alp.oktem.me/2025/11/21/mozfest</id><content type="html" xml:base="https://alp.oktem.me/2025/11/21/mozfest.html"><![CDATA[<p align="center"><img loading="lazy" src="/img/poble_espanyol.png" alt="Poble Espanyol in Barcelona during Mozilla Festival 2025" width="100%" style="margin:10px" />

</p>

<p><a href="https://www.mozillafestival.org/en/" target="_blank">Mozilla Festival</a> happened right in my own neighborhood in Barcelona this year—three days of conversations that put me up to date where ethical technology is heading. And also where my work is situated among all this.</p>

<p>This wasn’t your typical conference with talks and panels, but workshops, hackathons, art installations, pilates, even a fashion show. The venue was Poble Espanyol, an enchanting miniature Spanish architecture-themed park that I always appreciate visiting as long as I don’t pay their usual pricey entrance fee. Imagine one session being in the back of a theater, then in the art museum and then at the back of a chapel.</p>

<p>The theme was “Unlearning,” and the crowd matched it: grassroots language organizations like Dagbani Wikimedians User Group and Te Hiku Media, civic tech labs like data_labe, Masakhane, researchers from Makerere University and University of South Africa, startups like Lelapa AI, Honcho, and Mozilla Foundation itself bringing it all together.</p>

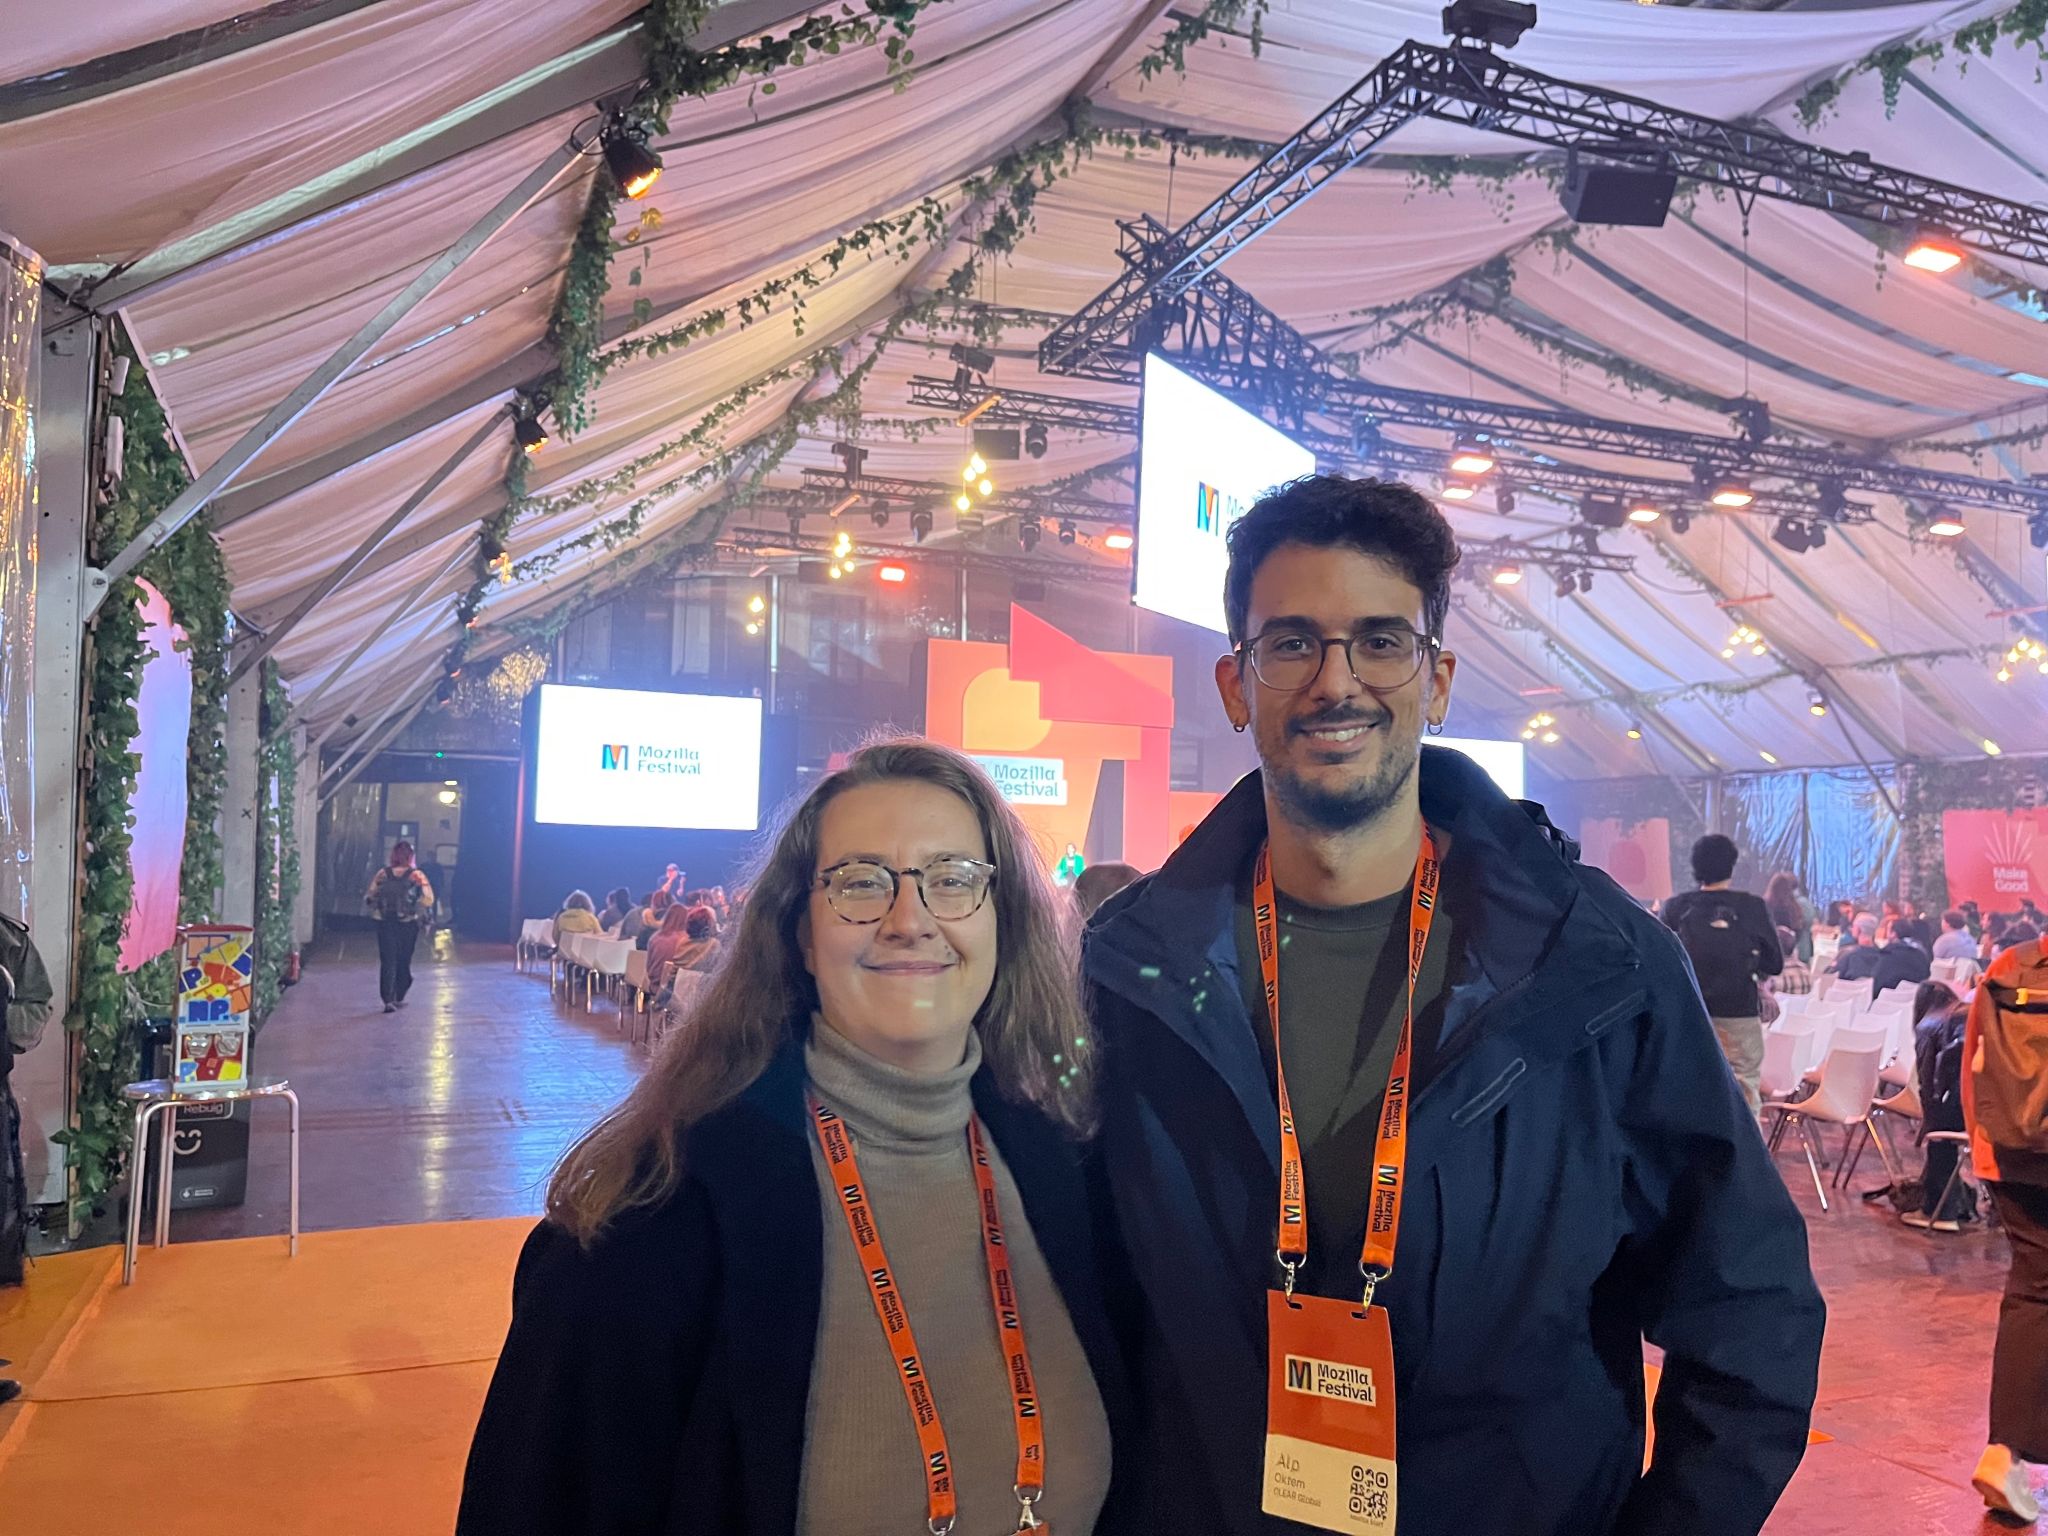
<p>Getting to be there in person with my CLEAR Global colleague Polly Harlow was definitely the highlight—after years of collaborating remotely. I hope we were able to synthesize our learnings and gave our team a fresh update on the landscape. <em>And the landscape is shifting fast</em>!</p>

<p>A shoutout to Francis Tyers for making it possible for us to attend. He’s been a collaborator since our work putting Aranese on Common Voice years ago and is now doing key work with Mozilla Data Collective and Common Voice. It was great to finally meet him and other folks from Common Voice in person.</p>

<p>A striking thing we noticed was that the notion “More data = better” is being challenged everywhere. The AI Data Real Talk session made this concrete. Keoni Mahelona from Te Hiku Media sat beside a Meta representative and essentially said: “we don’t want you to have our data, and if you want to work on our language, go marry a Māori person, and I’m serious.” Now that’s data sovereignty, not as theory but as practice.</p>

<p>The licensing ecosystem is exploding—<a href="https://licensingafricandatasets.com/" target="_blank"><strong>NOODL</strong></a>, <a href="https://arxiv.org/abs/2502.15916" target="_blank"><strong>Esethu</strong></a>, <a href="https://kaituhi.nz/kaitiakitanga" target="_blank"><strong>Kaitiakitanga</strong></a> frameworks are all trying to encode community ownership into legal infrastructure. It was especially a pleasure to meet Lilian D. Wanzare from Maseno Centre for Applied Artificial Intelligence who walked me through NOODL’s vision while having our pizza together. Creative Commons just launched <a href="https://creativecommons.org/2025/06/25/introducing-cc-signals-a-new-social-contract-for-the-age-of-ai/" target="_blank"><strong>CC Signals</strong></a>, an updated open licensing framework adapted for the AI age. <a href="https://datacollective.mozillafoundation.org/" target="_blank"><strong>Mozilla Data Collective</strong></a> officially launched their platform, positioned to help communities actually implement these types of custom licenses. I saw that they’re already hosting valuable datasets, and we’re in continued conversations about potentially hosting CLEAR Global’s <a href="https://huggingface.co/datasets/CLEAR-Global/TWB-Voice-1.0" target="_blank"><strong>TWB Voice dataset</strong></a> there.</p>

<p>I never fathomed earlier how key the work of <a href="https://commoncrawl.org/" target="_blank"><strong>Common Crawl</strong></a> is in today’s AI boom. Pedro Ortiz Suarez explained how they’re actively making their crawls more inclusive—asking language communities to share URLs of pages in their language rather than sticking to US-centric scraping of the web. A tiny non-profit running the infrastructure that powers so much of what we see today as “AI.”</p>

<p>I also had the chance to speak with startups working on AI-powered applications for local languages, not just data infrastructure. My impression is that making and commercializing sovereign technology is hard. It was both sad but assuring to hear that promising initiatives still struggle to turn their work into stable income, relying on public funding or equity investment rather than sustainable revenue. I say assuring because this validates the exact challenge I faced with my recently closed cooperative (more on that later). We developed open-source ASR, TTS, and MT models for languages like Catalan, Galician, and Judeo-Spanish, envisioning they would power AI applications. They didn’t get picked up beyond occasional artistic installations and prototype apps. And it’s not just us—even state-funded research organizations’ models sit unused. I guess it needs time, but my other impression is that only big tech cloud APIs are seen as trustworthy enough for real-world integrations like say telephone IVR. Something worth exploring deeper in another post.</p>

<p>These three days helped me see where we actually are in building an inclusive digital world—not just the promising developments, but the gaps we still need to address. The distance between big tech and localized initiatives is massive, but it’s promising to see serious work happening across the spectrum.</p>

<p>And finally, the mandatory festival photo with my dear colleague Polly…</p>

<p align="center"><img loading="lazy" src="/img/mozfest.jpg" alt="Alp and Polly, his colleague from CLEAR Global, at Mozilla Festival main stage" width="100%" style="margin:10px" />

</p>]]></content><author><name>Alp Öktem</name></author><category term="Conference" /><category term="Data Licensing" /><summary type="html"><![CDATA[Data Sovereignty as Practice, Not Theory]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/poble_espanyol.png" /><media:content medium="image" url="https://alp.oktem.me/img/poble_espanyol.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Promises of Large Language Models: From virtual companions to catalysts for education and language preservation</title><link href="https://alp.oktem.me/2025/10/23/llmdemo.html" rel="alternate" type="text/html" title="Promises of Large Language Models: From virtual companions to catalysts for education and language preservation" /><published>2025-10-23T09:00:00+00:00</published><updated>2025-10-23T09:00:00+00:00</updated><id>https://alp.oktem.me/2025/10/23/llmdemo</id><content type="html" xml:base="https://alp.oktem.me/2025/10/23/llmdemo.html"><![CDATA[<p><em>This post was originally published as part of CollectivaT’s tech blog. I’m republishing it here on my personal blog to consolidate my technical writing in one place.</em></p>

<p><br /></p>

<p align="center"><img loading="lazy" src="/img/llm-post-header.png" alt="3D illustration of a child talking to an animated character on a computer" width="100%" style="margin:10px" />

</p>

<p>In our last post, we introduced the <strong>Col·lectivaT Tech Lab</strong>, an initiative designed to share our insights, prototypes, and vision for language technology with the broader community. Today, we’re excited to take you further into this journey, with a focus on <strong>Large Language Models (LLMs)</strong> and their transformative potential in fields like education and language preservation. We’ll also present our demo of Bo, the open-source software-loving dog, that we’ve been working on, which demonstrates the conversational capabilities of LLMs.</p>

<h3 id="what-are-large-language-models">What are Large Language Models?</h3>

<p><strong>Large Language Models (LLMs)</strong>  is one of the <strong>most recent and most impactful development in Artificial Intelligence (AI)</strong>, especially within the domain of <strong>natural language processing (NLP)</strong>. These models are the latest evolution in language modeling, designed to capture the contextual relationship between words. This enables LLMs to generate coherent, context-sensitive responses, moving beyond mere pattern recognition to perform <strong>complex tasks such as conversation, translation, and content creation</strong> with remarkable fluency and adaptability.</p>

<!-- <p align="center"><img loading="lazy" src="/img/blog/2024/pexels-googledeepmind-18069696.jpg" alt="Una ilustracion" width="70%" style="margin:10px">
</p>
 -->
<p>From language translation to content creation, LLMs have quickly become a <strong>powerful tool that automates complex processes and tasks</strong> in professional environments, <strong>improving efficiency across various sectors such as customer service, marketing, and data analysis</strong>. Recent advancements have pushed these capabilities even further, enabling these models to handle more nuanced and complex conversations, as well as process and generate audio, images, and video.</p>

<h3 id="exploring-use-of-llms-for-social-transformation">Exploring use of LLMs for social transformation</h3>

<p>At <strong>Col·lectivaT</strong>, we are particularly interested in how language technologies can be harnessed for <strong>social</strong> <strong>transformation</strong>. For instance, can LLMs be adapted to serve <strong>lower-resourced languages</strong>, which often lack sufficient digital representation? Could they help <strong>preserve marginalized languages by providing more accessible tools for learning and communication</strong>? These are the kinds of questions that drive our most recent experimentation.</p>

<h3 id="talk-with-bo-your-virtual-companion-passionate-for-open-source">Talk with Bo: Your virtual companion passionate for open-source</h3>

<p>We invite you to explore <a href="https://bodemo-delta.vercel.app/" target="_blank">our latest demo</a>, where you will interact with Bo, a friendly virtual dog powered by an LLM passionate about open-source software. To start talking with him, you just need to click on the microphone button, say ‘Hello’ and let the conversation flow. Bo will listen to you, answer your questions, and propose new ones to help you dive deeper into the topic you’re discussing.</p>

<p>By conversing with Bo, you’ll not only <strong>learn about open-source software</strong>, but you’ll also connect with it through your own experience. If you don’t have any knowledge of coding or programming, Bo will use examples from his world to make it more understandable. As the conversation progresses, you may discover you know more than you thought. If you’re already experienced in this field and mention an open-source project or repository, Bo will be excited to talk about it in depth, using the knowledge he draws from the language model he operates on.</p>

<h3 id="how-does-it-work-the-technology-behind-bo">How Does It Work? The Technology Behind Bo</h3>

<p>This demo app is based on open-source code originally developed by Google to demonstrate the conversational capabilities of LLMs. We’ve adapted the code to suit our purposes by localizing the character to <strong>Catalan</strong>, giving Bo a <strong>unique history and background that reflects our local context</strong>. You can explore Bo’s personality and backstory in the configuration panel if you’re curious about it, accessible through the upper menu.</p>

<p>Multiple technologies work together to bring Bo to life. <strong>Automatic Speech Recognition (ASR)</strong> converts your spoken words into text. That text, along with Bo’s personality details, is processed by the LLM backend to create a meaningful, context-aware response. Finally, <strong>Text-to-Speech (TTS)</strong> technology converts Bo’s replies into spoken words, giving him a voice. The animation adds a visual <strong>touch that mimics an actual conversation</strong>, making the interaction feel more natural and engaging, as if you’re chatting with a real companion.</p>

<p>It’s hard not to notice Bo’s American English accent. This is due to the <strong>English-centric training</strong> of OpenAI’s TTS models. However, if you ask Bo about his owner, you’ll discover an intriguing twist to his linguistic background and how he become to be so fond of open source software!</p>

<p>Unlike traditional virtual assistants, Bo’s responses are not pre-programmed or stored—they are generated on the fly, based on the flow of interactions. This makes his conversations much more dynamic and fluid, without the rigid scripts typical of systems like banking assistants.</p>

<p><em>While we’re currently using OpenAI’s APIs for the sake of convenience in this experimentation, we’re committed to moving towards fully <strong>open-source alternatives</strong> that better align with our <strong>values of accessibility and transparency</strong> in the long run.</em></p>

<h3 id="beyond-bo-potential-applications-for-social-good">Beyond Bo: Potential applications for social good</h3>

<p>How can a <strong>LLM-powered virtual character</strong> like Bo serve as a <strong>tool for social transformation</strong>? While commercial applications often focus on customer service or personalized marketing, we at Col·lectivaT, place value on its tremendous potential for such applications to positively impact areas like language preservation, <strong>education</strong> and <strong>social awareness</strong>.</p>

<p>One exciting application is in <strong>language learning</strong>, especially for <strong>minorized languages</strong> that often lack the resources for comprehensive study and practice. Children learning these languages might only have limited exposure in school or at home. A fun, interactive companion like Bo can offer a much-needed space to practice, reinforcing the use of their language in <strong>engaging, pressure-free ways</strong>. Learners can converse without fear of making mistakes. This virtual interaction creates an opportunity to <strong>explore and play with language</strong>, helping bridge the gap where traditional resources fall short.</p>

<p>Beyond language learning, conversational companions can open the door to personalized conversations on topics like <strong>climate change</strong>, <strong>menstrual health</strong>, <strong>addiction</strong>, or <strong>LGBTI issues</strong>—topics that kids might find difficult to talk about with teachers or parents. These virtual companions provide a safe space for children and teens where no question is too embarrassing or awkward to ask.</p>

<p>We must say that this isn’t about replacing teachers or caregivers, but about <strong>complementing them and scaling their efforts within their oversight</strong>. Virtual companions can provide a <strong>judgment-free, personalized learning environment</strong>—whether that’s in practicing a language, discussing sensitive issues, or simply interacting with technology in a more intuitive way.</p>

<h3 id="moving-forward">Moving forward</h3>

<p>As we look ahead, we’re eager to continue experimenting with the platform, testing its capabilities and limitations. Our technical next steps include integrating the latest <strong>open sourced LLaMA models</strong> to enhance the language capabilities and refining <strong>our in-house text-to-speech models</strong> to ensure more natural and localized voice interactions. We’ll also explore how to seamlessly integrate these solutions into educational and social settings.</p>

<p>We’d love to hear your thoughts! If you’ve interacted with Bo or have ideas for how this technology can evolve, <strong>please reach out and share your feedback.</strong></p>

<p>We’d also like to thank <a href="https://yuxuanize.vercel.app/" target="_blank"><strong>Yuxuan Peng</strong></a>, a full-stack web developer from our <a href="https://awaldigital.org/" target="_blank"><strong>Awal</strong></a> initiative, for his invaluable volunteer contributions to this project.</p>]]></content><author><name>Alp Öktem</name></author><category term="LLM" /><category term="Education" /><summary type="html"><![CDATA[How Large Language Models can transform education and language preservation]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/llm-post-header.png" /><media:content medium="image" url="https://alp.oktem.me/img/llm-post-header.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Can LLMs Help Revitalize an Endangered Language?</title><link href="https://alp.oktem.me/2025/07/04/estreyika.html" rel="alternate" type="text/html" title="Can LLMs Help Revitalize an Endangered Language?" /><published>2025-07-04T09:00:00+00:00</published><updated>2025-07-04T09:00:00+00:00</updated><id>https://alp.oktem.me/2025/07/04/estreyika</id><content type="html" xml:base="https://alp.oktem.me/2025/07/04/estreyika.html"><![CDATA[<p align="center"><img loading="lazy" src="/img/estreyika.png" alt="Estreyika Perez chatbot interface showing conversation in Ladino" width="100%" /></p>

<p>Can LLMs help revitalize an endangered language? That’s exactly what we’re exploring in my latest collaboration creating a chatbot that speaks and helps practice Ladino: Estreyika Perez.</p>

<p>Today marks her launch and you can listen to our conversation with the Estreyika team and see her capabilities in action. I’m delighted to see this becoming reality as this represents a major leap from when we first created the <a href="http://translate.sefarad.com.tr" target="_blank">automatic translator for Ladino</a> in 2022. Seeing fluent conversations happening to help people practice this severely endangered Judeo-Spanish language (UNESCO lists only ~50,000 speakers worldwide) is incredible progress!</p>

<h2 id="from-skepticism-to-success">From Skepticism to Success</h2>

<p>When Dr. Carlos Yebra López first contacted me with his idea, I really thought this wouldn’t be possible but gave it a chance thinking our rule-based translator would help. The challenge seemed immense - how could we create a conversational AI for a language with such limited digital resources?</p>

<p>At the end, it turns out that modern LLMs know at least something of Ladino and with the right optimization and linguistic knowledge push, we can obtain a compelling conversational experience. This discovery opened up possibilities we hadn’t initially imagined.</p>

<h2 id="building-on-digital-foundations">Building on Digital Foundations</h2>

<p>This breakthrough is thanks to both technological advancements of LLMs, but beyond that, the amazing work by linguists and activists who’ve built Ladino’s digital presence over the years. Our previous work on machine translation and text-to-speech synthesis for Ladino, published in <a href="/publications/2022-06-21-EURALI/">“Preparing an Endangered Language for the Digital Age”</a>, laid crucial groundwork for this project.</p>

<p>The technical challenge was significant. Unlike our MT project where we could build rules to translate from one language to another, a real conversation requires a deep understanding of cultural context, authentic language use, and the ability to maintain character consistency throughout extended dialogues. This is now possible with the advent of LLMs but still we had to carefully craft prompts to ensure Estreyika doesn’t fall into “Spanishisms” - using Spanish grammar patterns or vocabulary that would feel inauthentic to native Ladino speakers - or provide inaccurate information.</p>

<h2 id="community-response-and-cultural-authenticity">Community Response and Cultural Authenticity</h2>

<p>The feedback from students and the community has been remarkable - many praising Estreyika’s authenticity in Ladino, her captivating personality, and her genuine enthusiasm that makes learning feel like chatting with a knowledgeable friend from 19th century Istanbul.</p>

<p>What strikes me most about the user feedback is how Estreyika manages to embody not just the language, but the cultural essence of Sephardic heritage. Students report feeling emotionally connected to the conversations, learning not just vocabulary but traditions, recipes, and historical context that brings the language to life.</p>

<h2 id="the-path-forward">The Path Forward</h2>

<p>This is just a pilot, but it validates our approach. Thrilled to continue pushing the boundaries of what’s possible when AI meets language revitalization. The success of Estreyika demonstrates that even severely endangered languages can benefit from modern language technology - not to replace human speakers, but to create new pathways for cultural transmission and learning.</p>

<h2 id="try-estreyika-yourself">Try Estreyika Yourself</h2>

<p>🎥 Watch the full presentation with demo: <a href="https://www.youtube.com/watch?v=ECWAAmWf_Ng">YouTube</a></p>

<p>💬 Chat with Estreyika: <a href="https://t.me/EstreyaLadinobot">Telegram Bot</a></p>]]></content><author><name>Alp Öktem</name></author><category term="LLM" /><category term="Language Revitalization" /><summary type="html"><![CDATA[Building the world's first conversational Ladino chatbot to preserve Judeo-Spanish heritage]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/estreyika.png" /><media:content medium="image" url="https://alp.oktem.me/img/estreyika.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">MT Rwanda - Pushing Forward Language Tech in Kinyarwanda</title><link href="https://alp.oktem.me/2023/09/28/kigali.html" rel="alternate" type="text/html" title="MT Rwanda - Pushing Forward Language Tech in Kinyarwanda" /><published>2023-09-28T09:00:00+00:00</published><updated>2023-09-28T09:00:00+00:00</updated><id>https://alp.oktem.me/2023/09/28/kigali</id><content type="html" xml:base="https://alp.oktem.me/2023/09/28/kigali.html"><![CDATA[<p align="center"><img loading="lazy" src="/img/mt_rwanda_demo.png" alt="Demoing MT for the sentence Good morning, could you please take me to the best place to eat Ikisafuriya in Kigali?" width="100%" /></p>

<p>I’ve always been inspired by traveling, and my favorite part of it is savoring the local dishes. Last week, I had the chance to do just that in Kigali, Rwanda, while I was attending the closing session of our project, “MT Rwanda.” I’m excited because the results of this project will undoubtedly make it easier for me to ask local taxi drivers to take me to the best restaurants in town the next time I visit this impressive country.</p>

<p>In this blogpost, I will share some exciting details and learnings on community data collection, multilingual model fine-tuning, and the close collaboration of two dynamic teams: <a href="https://clearglobal.org/">CLEAR Global</a> and <a href="https://digitalumuganda.com/">Digital Umuganda</a>, pushing forward language technology for Kinyarwanda.</p>

<h2 id="mt-rwandas-mission">MT Rwanda’s Mission</h2>

<p>Our mission in “MT Rwanda” was nothing short of groundbreaking: to boost open-source machine translation (MT) for impact in Kinyarwanda. This Rwandan language is spoken by millions and is central to the culture and identity of the nation. The project’s primary focus areas for impact were education and tourism, with a clear aim to bridge linguistic gaps and empower local communities.</p>

<p>In this endeavor, I had the privilege of mentoring the Rwandan AI company, Digital Umuganda, on data collection and MT model development. They had already been diligently pioneering open-source Kinyarwanda language technology for quite some time now. Thanks to their community efforts, Kinyarwanda has gained quite a few open-source datasets. The most notable of these is definitely their <a href="http://commonvoice.mozilla.org/">Common Voice</a> campaign, which placed Kinyarwanda in the top 5 in terms of the number of speech hours collected.</p>

<p>This time, the task was to push towards improving machine translation for this language. Kinyarwanda is one of the languages supported in Google Translate. It’s also supported in the multilingual <a href="https://ai.meta.com/research/no-language-left-behind/">No Language Left Behind (NLLB)</a> model released by Meta. However, all these models lack the quality to ensure reliability in real-world solutions, as many low-resource languages do. We needed to ensure they perform up to expectations in two real-life use-cases.</p>

<h2 id="the-power-of-community-driven-data">The Power of Community-Driven Data</h2>

<p>One of the most exciting aspects of this project was the data collection campaign. To train the MT models effectively, we needed a substantial amount of high-quality parallel data. What made this campaign stand out was the community-driven approach adopted. With the enthusiastic participation of volunteers, we managed to collect over <a href="https://huggingface.co/datasets/mbazaNLP/NMT_Education_parallel_data_en_kin">60,000 sentence translations</a>.</p>

<p>The source sentences to translate were crawled automatically from sites related to tourism (e.g. wikitravel, booking.com, tripadvisor), both in English and Kinyarwanda, and also web content we collected on finance, business, and economy-related articles on Wikipedia, Atingi, and Coursera. The source data can be accessed from <a href="https://huggingface.co/datasets/DigitalUmuganda/monolingual_machine_translation_data">this repository on Hugging Face</a> and the <a href="https://github.com/Digital-Umuganda/machine_translation_data_scraping">scrapers on GitHub</a>.</p>

<h2 id="open-source--collective-ownership">Open source = Collective ownership</h2>

<p>In this project, we underscored the importance of open-source language technology. We started with Meta’s No Language Left Behind (NLLB) model as our base, trained with over 10 million web-crawled Kinyarwanda sentence translations as well as supporting 200 languages. Our approach involved a two-stage training process. In the first stage, we utilized diverse data from general, education, and tourism domains to enhance the model’s overall performance. Then, in the second stage, we specialized the model for education and tourism separately. All training was conducted bidirectionally, and you can find the fine-tuning training and testing scripts in this <a href="https://github.com/Digital-Umuganda/twb_nllb_project_tourism_education">Github repository</a> for a closer look.</p>

<p>The project’s commitment to open-source principles means that all the data and models we created are openly accessible to anyone interested in Kinyarwanda language technology. This also ensures reproducibility and collaboration from external collaborators to carry the flag forward. You can find these valuable resources on HuggingFace, complete with demos that showcase their capabilities: Education <a href="https://huggingface.co/mbazaNLP/Nllb_finetuned_education_en_kin">model</a> and <a href="https://huggingface.co/spaces/mbazaNLP/Finetuned-NLLB-EDUCATION-EN-KIN">demo</a>, Tourism <a href="https://huggingface.co/mbazaNLP/Nllb_finetuned_tourism_en_kin">model</a> and <a href="https://huggingface.co/spaces/mbazaNLP/Finetuned-NLLB-TOURISM-EN-KIN">demo</a>.</p>

<h2 id="what-lies-ahead">What Lies Ahead</h2>

<p>As we wrap up this transformative project, our sights are set on the future. We’re eager to publish a technical paper soon, sharing our insights, challenges, and triumphs with the wider research community. Collaborating with Digital Umuganda has been a rewarding experience, and I’m quite enthusiastic about collaborating with them further on.</p>

<p>My impression from our end-of-project session in Kigali is that the road ahead for Kinyarwanda is filled with promise. Together, we have identified many interesting ideas and also challenges to bring the initiative forward. I’m looking forward to witnessing and being part of further advancements in open-source Kinyarwanda language technology and its potential in creating an impact for Rwanda. And of course, making more opportunities to visit and explore further the delicious Rwandan cuisine.</p>

<p align="center"><img loading="lazy" src="/img/Ikisafuriya.jpg" alt="Trying Ikisafuriya for the first time" width="60%" /></p>
<p align="center">My colleague Geo couldn't resist taking a snap of my happy face trying Ikisafuriya for the first time. It was finger-licking good!</p>]]></content><author><name>Alp Öktem</name></author><category term="MT" /><category term="Travel" /><summary type="html"><![CDATA[So that I can find the best local food in Kigali next time I visit]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/mt_rwanda_demo.png" /><media:content medium="image" url="https://alp.oktem.me/img/mt_rwanda_demo.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">CATOTRON.cat launched</title><link href="https://alp.oktem.me/2021/11/19/catotron.html" rel="alternate" type="text/html" title="CATOTRON.cat launched" /><published>2021-11-19T09:00:00+00:00</published><updated>2021-11-19T09:00:00+00:00</updated><id>https://alp.oktem.me/2021/11/19/catotron</id><content type="html" xml:base="https://alp.oktem.me/2021/11/19/catotron.html"><![CDATA[<p>This week, my cooperative Col·lectivaT has launched the new version of Catotron with a slick new web app <a href="http://catotron.cat">catotron.cat</a>. Catotron is the first open-source, neural network-based speech synthesis engine for Catalan. It’s built with support from Department of Culture of Catalan Government and was <a href="/publications/2020-10-25-interspeech20/">published earlier in Interspeech 2020</a>.</p>

<p align="center"><img loading="lazy" src="/img/catotron_banner.png" alt="CATOTRON logo" width="100%" /></p>

<p>Catotron is a great example of people-oriented and people-driven language technology. It will prevent the exclusion of Catalan speakers from using speech-interfaced technology like voice assistants, GPS, Telephone IVR etc.</p>

<p>I am very excited to see that Catalan media outlets are celebrating its launch with us. Among some of them:</p>

<ul>
  <li><a href="https://www.metadata.cat/noticia/1772/catotron-renova-sintesi-veu-catala">Catotron es renova per impulsar la síntesi de veu en català</a> by Metadata.cat</li>
  <li><a href="https://www.diarimes.com/noticies/actualitat/catalunya/2021/11/16/siri_alexa_catala_una_nova_eina_facilita_113591_3029.html">Siri o Alexa en català? Una nova eina ho facilita</a> by Diari més</li>
  <li><a href="https://www.larepublica.cat/minut-a-minut/la-cooperativa-collectivat-crea-el-primer-motor-de-sintesi-de-veu-en-catala/">La cooperativa Col·lectivaT crea el primer motor de síntesi de veu en català</a> by La República</li>
  <li><a href="https://www.naciodigital.cat/noticia/227058/primer-motor-sintesi-veu-catala-realitat">El primer motor de síntesi de veu en català ja és una realitat</a> by Nació digital</li>
  <li><a href="http://www.elpuntavui.cat/societat/article/5-societat/2058796-la-cooperativa-col-lectivat-crea-el-primer-motor-de-sintesi-de-veu-en-catala.html?cca=3">La cooperativa Col·lectivaT crea el primer motor de síntesi de veu en català</a> by El Punt Avui</li>
</ul>]]></content><author><name>Alp Öktem</name></author><category term="Speech" /><category term="TTS" /><summary type="html"><![CDATA[Towards a catalanoparlant future for speech technology]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/catotron_banner.png" /><media:content medium="image" url="https://alp.oktem.me/img/catotron_banner.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Corpora compilation for prosody-informed speech processing</title><link href="https://alp.oktem.me/2021/10/30/lre.html" rel="alternate" type="text/html" title="Corpora compilation for prosody-informed speech processing" /><published>2021-10-30T09:00:00+00:00</published><updated>2021-10-30T09:00:00+00:00</updated><id>https://alp.oktem.me/2021/10/30/lre</id><content type="html" xml:base="https://alp.oktem.me/2021/10/30/lre.html"><![CDATA[<p>My article <a href="/publications/2021-09-04-LRE/">“Corpora compilation for prosody-informed speech processing”</a> was finally published in Language Resources &amp; Evaluation journal (LRE) after a long period of back and forth with the reviewers. The paper is like a TL;DR (too long didn’t read) version of my thesis where I give a summary of all the tools, datasets and experiments that came out of my PhD research, which dealt with the basically the question: <em>How can we incorporate non-verbal information like prosody in machine translation and transcription?</em></p>

<p>For those who read “prosody” twice there, it refers to the “music-like” aspects in speech, which correspond to intonation, rhythm and stress. While words carry “what” is said in an utterance, prosody deals with “how” they are delivered.</p>

<p align="center"><img loading="lazy" src="/img/lre/prosody-features.png" alt="pause, intonation, intensity, speech rate" width="60%" /></p>

<p>In this post, I’m giving a further TL;DR for the fast researchers out there. You can follow links to respective papers and libraries if you’re interested.</p>

<p><br /></p>

<h2 id="prosodically-annotated-ted-talks">Prosodically annotated TED Talks</h2>

<p><br /></p>

<p>To begin my studies, I needed a big corpus to study and train machine learning models based on prosody. I created <a href="hdl.handle.net/10230/33981">Prosodically annotated TED Talks (PANTED) corpus</a> based on my supervisor Mireia Farrus’s version and augmented with additional prosodic and syntactic information.</p>

<p><br /></p>

<p align="center"><img loading="lazy" src="/img/lre/panted.png" alt="PANTED corpus consists of 1038 talks from 877 speakers uttering 155174 sentences in total" width="70%" /></p>

<h2 id="punctuation-restoration-with-prosody">Punctuation restoration with prosody</h2>

<p><br /></p>

<p>The whole reason behind creating PANTED was to see the effect of prosody on the punctuation restoration task. It showed that pausing and intonation information can improve the automatic punctuation of ASR output. (<a href="publications/2017-10-23-slsp/">Original paper</a>, <a href="https://github.com/alpoktem/punkProse">punkProse code</a>)</p>

<p><br /></p>

<p align="center"><img loading="lazy" src="/img/lre/punkScores.png" alt="Effect of each prosodic/syntactic feature in prediction of different punctuation marks" width="70%" /></p>

<h2 id="proscript">Proscript</h2>

<p><br /></p>

<p>At some point, I realized how painful it was working with Praat and TextGrids when doing machine learning, so I created my own data structure and visualizer. Proscript helps represent speech with segment-level prosodic features in a tidy CSV file. Python library in <a href="https://github.com/alpoktem/proscipt">Github</a>.</p>

<p align="center"><img loading="lazy" src="/img/lre/proscript1.png" alt="Segmental prosodic features in a speech audio" width="90%" /></p>

<p><br /></p>

<h2 id="prosograph">Prosograph</h2>

<p><br /></p>

<p>Prosograph enables manual examination of Proscripts along with their audio by visualizing speech-related characteristics besides words similar to a musical scoreMusical score. It’s programmed in Processing and is accessible <a href="https://github.com/alpoktem/Prosograph">from github</a>.</p>

<p align="center"><img loading="lazy" src="/img/lre/prosograph.png" alt="Prosograph visualizing a TED talk" width="90%" /></p>

<p><br /></p>

<h2 id="movie2paralledb">movie2paralleDB</h2>

<p><br /></p>

<p>I wanted to go into translation from the beginning of my PhD, although I knew it might be a bit tough. Not having any parallel speech corpora around didn’t stop me of course. I built <a href="https://github.com/alpoktem/movie2parallelDB">movie2parallelDB</a> to make corpora automatically, out of dubbed movies and series.</p>

<p align="center"><img loading="lazy" src="/img/lre/movie2parallelDB.png" alt="Pipeline for building parallel speech corpus from dubbed movies" width="100%" /></p>

<p><br /></p>

<h2 id="heroes-corpus">Heroes Corpus</h2>

<p><br /></p>

<p>The result of this was <a href="http://hdl.handle.net/10230/35572">Heroes corpus</a>, an English-Spanish parallel movie speech corpus made out of my childhoods popular series <em>Heroes</em>. 
We showed in the paper how silence information can improve spoken machine translation.</p>

<p><br /></p>

<p align="center"><img loading="lazy" src="/img/lre/heroes-corpus.png" alt="Heroes corpus contains 7000 English-Spanish parallel segments totaling to 9.5 hours of bilingual speech and is available with open access" width="75%" /></p>

<p>I also earlier explained about how I used this corpus in <a href="/2019/12/15/machinedub.html">building a prosody-informed machine dubbing setup</a>.</p>]]></content><author><name>Alp Öktem</name></author><category term="Speech" /><category term="Prosody" /><summary type="html"><![CDATA[A TL;DR on my latest journal paper and PhD]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/lre/proscript1.png" /><media:content medium="image" url="https://alp.oktem.me/img/lre/proscript1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Personal highlights from EMNLP 2020</title><link href="https://alp.oktem.me/2020/11/23/emnlp.html" rel="alternate" type="text/html" title="Personal highlights from EMNLP 2020" /><published>2020-11-23T12:01:00+00:00</published><updated>2020-11-23T12:01:00+00:00</updated><id>https://alp.oktem.me/2020/11/23/emnlp</id><content type="html" xml:base="https://alp.oktem.me/2020/11/23/emnlp.html"><![CDATA[<p align="center"><img loading="lazy" src="/img/emnlp-header.png" alt="Text 'EMNLP 2020 The 2020 Conference on Empirical Methods in Natural Language Processing 16th – 20th November 2020' on top of an image of the earth by NASA" width="100%" /></p>

<p>In this post I tried to compile some nice papers that I came across in EMNLP 2020 together with the work that I collaborated with. I’ve curated the list with a focus on machine translation and transcription of under-represented languages.</p>

<p>Some personal notes first: This conference was a first for me in a couple of ways. Firstly, it was the first major NLP conference that I participated. Secondly, it was my first fully-virtual multi-day conference. Despite a couple of technical hick-ups, I found the virtual setup to function rather well for me connecting from my cozy home. It’s really nice to see that it is possible to organize events of this scale given the circumstances of the pandemic.</p>

<p>Although, I have to say the experience was incomparable to a presential conference. Strolling through links, chatboards and virtual environments barely replaces the constant flow you experience in the physical conference setup. I am looking forward to see hybrid setups in the future combining presential and virtual participation. I actually believe a virtual alternative has long been due for conferences, regardless of the pandemic. Why? First, virtual participation allows saving a tons of carbon generated from avoidable travel. Second, it is a half-way remedy for researchers that face financial, parental and visa restrictions.</p>

<p>Regarding the content, I was very very happy to see this amount of work on the under-resourced language spectrum. Though, I am probably biased since that was the kind of work I was looking out for. I am not so sure of the diversity of languages represented in the conference. I would love to see a report on that the coming days.</p>

<p>I’d like to start the list with the work that I have collaborated with. Both are motivated by the purpose of bringing NLP and language technology to marginalized and under-represented languages and gives me hope and inspiration for the future of NLP research. I am looking forward to see more and be part of transversal and disruptive collaborations like these.</p>

<h4 id="masakhane---participatory-research-for-low-resourced-machine-translation-a-case-study-in-african-languages-paper-keynote-video"><a href="/publications/2020-11-16-emnlp/">Masakhane - Participatory Research for Low-resourced Machine Translation: A Case Study in African Languages</a> (<a href="https://www.aclweb.org/anthology/2020.findings-emnlp.195/">Paper</a>, <a href="https://youtu.be/Xbc_g_OknqA">Keynote video</a>)</h4>

<p>Masakhane is a cross-border, inclusive, grassroots organisation with a decolonial mindset and a stand against the inherent professionalism, anglo-centricity and academic dominance in the NLP field. They promote a participatory and accessible NLP research methodology and showcase it for languages of Africa. A continent that has been unfortunately but unsurprisingly left mostly blank in terms of coverage in NLP research. The paper rejects the notion of “low-resourcedness” as a mere question of data availability and brings into light many aspects that drive a language into this category. 48+ professional and non-professional researchers has worked together to reverse that while publishing benchmarks for 30+ African languages, evaluations, datasets and open-sourced implementations. – <a href="https://www.masakhane.io/">https://www.masakhane.io/</a></p>

<p align="center"><img loading="lazy" src="/img/masakhane.jpg" alt="Masakhane logo. Let us build together." width="70%" /></p>

<h4 id="tico-19-the-translation-initiative-for-covid-19-paper"><a href="/publications/2020-11-19-covid19/">TICO-19: the Translation Initiative for Covid-19</a> (<a href="https://www.aclweb.org/anthology/2020.nlpcovid19-2.5/">Paper</a>)</h4>

<p>The Translation Initiative for Covid-19 (TICO-19) came together shortly after the beginning of the Covid-19 pandemic with the aim of enabling the translation of content related to COVID-19 into a wide range of languages. It is a unique collaboration between several academic (Carnegie Mellon University, George Mason University, Johns Hopkins University) and industry players (Amazon, Appen, Facebook, Google, Microsoft, Translated) and Translators without Borders. TICO-19’s objective is to prepare data for a variety of the world’s languages to be used by professional translators and for training Machine Translation (MT) models in Covid-19 domain. – <a href="https://tico-19.github.io/">https://tico-19.github.io/</a></p>

<p>Here goes the papers that caught my eye during the conference. If you have more paper suggestions similar to these, please don’t hesitate to <a href="/about">drop me a note</a>.</p>

<h4 id="sparse-transcription---s-bird-paper-video">Sparse Transcription - S. Bird (<a href="https://www.mitpressjournals.org/doi/pdf/10.1162/COLI_a_00387">Paper</a>, <a href="https://slideslive.com/38939392">Video</a>)</h4>
<ul>
  <li>Approach transcription as observing, not data creation</li>
  <li>Phone recognition for transcripton is not enough. We need lexical information.</li>
  <li>Traditionally spoken languages are translated first, not literally translated</li>
  <li>Leverage keyword spotting instead of ASR</li>
  <li>Paper includes more on sparse transcription model:
    <ul>
      <li>data structure</li>
      <li>8 transcription tasks</li>
      <li>transcription workflows</li>
      <li>evaluations</li>
    </ul>
  </li>
</ul>

<h4 id="consistent-transcription-and-translation-of-speech--sperber-paper-video">Consistent Transcription and Translation of Speech – Sperber+ (<a href="https://www.mitpressjournals.org/doi/pdf/10.1162/tacl_a_00340">Paper</a>, <a href="https://slideslive.com/38939415">Video</a>)</h4>
<ul>
  <li>Objective: Obtain both transcript and translation of speech and make them consistent</li>
  <li>For evaluation, WER and BLEU by themselves are not enough because they do not measure consistency between the transcription and translation result.</li>
  <li>Propose metrics to evaluate consistency</li>
  <li>Evaluate on many models: cascaded, direct and joint models</li>
  <li>Data: Must-C Corpus (EN-DE)</li>
  <li>Joint models (see below) perform the best in terms of WER, BLEU and consistency</li>
  <li>Best of the best: Two-stage model</li>
  <li>Conclusion: Coupled inference and end-2-end training are desirable in speech translation</li>
</ul>

<p align="center"><img loading="lazy" src="/img/sperber-jointtranscription.png" alt="Joint model architectures. Image by Sperber+" width="70%" /></p>

<h4 id="chren-cherokee-english-machine-translation-for-endangered-language-revitalization--zhang-paper-video">ChrEn: Cherokee-English Machine Translation for Endangered Language Revitalization – Zhang+ (<a href="https://www.aclweb.org/anthology/2020.emnlp-main.43/">Paper</a>, <a href="https://slideslive.com/38938800">Video</a>)</h4>
<ul>
  <li>Obtain best possible model for bidirectional Cherokee-English MT</li>
  <li>Data: 14k parallel sentences (collected as part of the work)</li>
  <li>Results:
    <ul>
      <li>RNN performs better than transformer</li>
      <li>Out of domain gives half the BLEU</li>
      <li>Using BERT on En-Chr direction +0.5% BLEU</li>
      <li>SMT performs better with out-of-domain data</li>
      <li>A lot of monolingual data doesn’t necessarily help
  	- 5K backtranslated sentences give the best performance</li>
      <li>Cross-lingual transfer:
  	* Unrelated languages help
  	* Evaluated transferring vs. multilingual</li>
    </ul>
  </li>
  <li><a href="https://github.com/ZhangShiyue/ChrEn">Code and data</a></li>
</ul>

<h4 id="can-automatic-post-editing-improve-nmt--chollampatt-paper-video">Can Automatic Post-Editing Improve NMT? – Chollampatt+ (<a href="https://arxiv.org/pdf/2009.14395v1.pdf">Paper</a>, <a href="https://slideslive.com/38939321">Video</a>)</h4>
<ul>
  <li>Created new large-scale EN-DE post-editing corpus from movie subtitles
    <ul>
      <li>SubEdits: 161k triply-parallel corpus: src, mt, post-edit(pe)</li>
      <li>open source</li>
    </ul>
  </li>
  <li>How much improvement on NMT from the usage of post-editing data?
    <ul>
      <li>BLEU: 61.88 -&gt; 64.53 (+3%)</li>
      <li>Human evaluation scores: 3.4 -&gt; 3.9 (out of 5)</li>
      <li>Improvements start from a training corpus size of 25k triplets</li>
    </ul>
  </li>
  <li>How much artifical APE data help?
    <ul>
      <li>Artificial: take a parallel corpus, machine translate it, assume tgt as post-edit</li>
      <li>SubEscape corpus: 5.6 M triplets</li>
      <li>Marginal improvement (+0.06 BLEU)</li>
      <li>Artificial data doesn’t help by itself</li>
    </ul>
  </li>
  <li>Post-editing data improves only if it’s in the domain</li>
  <li><a href="https://github.com/shamilcm/pedra">Data: Post-editing Datasets by Rakuten (PEDRa)</a></li>
</ul>

<h4 id="simulated-multiple-reference-training-improves-low-resource-machine-translation--khayrallah-paper-video">Simulated multiple reference training improves low-resource machine translation – Khayrallah+ (<a href="https://arxiv.org/pdf/2004.14524.pdf">Paper</a>, <a href="https://slideslive.com/38938786">Video</a>)</h4>
<ul>
  <li>Data augmentation for NMT by paraphrasing of target side sentences</li>
  <li>Record increase in quality (more than what you get from back-translation)</li>
  <li>State that paraphrasers are getting more and more available for languages.
    <ul>
      <li><a href="https://github.com/thompsonb/prism">PRISM paraphraser</a> in 39 languages</li>
    </ul>
  </li>
  <li><a href="http://data.statmt.org/smrt/">Data</a></li>
</ul>

<h4 id="bleu-might-be-guilty-but-references-are-not-innocent--freitag-paper-video">BLEU might be Guilty but References are not Innocent – Freitag+ (<a href="https://arxiv.org/abs/2004.06063">Paper</a>, <a href="https://slideslive.com/38938647">Video</a>)</h4>
<ul>
  <li>Observation: BLEU doesn’t show the improvement obtained from techniques like back-translation</li>
  <li>Propose: When BLEU seems to act weird, revise the reference translations</li>
  <li>Detected problem: Reference translations tend to be in translationese
    <ul>
      <li>:= imitating the structure of the source sentence</li>
    </ul>
  </li>
  <li>MT model strives to be the most average translationese</li>
  <li>When you improve fluency with methods like back-translation or automatic post-editing, BLEU conditioned on translationese doesn’t show the improvement even though human evaluations do</li>
  <li>Solution: paraphrase the reference sentences</li>
</ul>]]></content><author><name>Alp Öktem</name></author><category term="NLP" /><category term="Conference" /><summary type="html"><![CDATA[Notes on the NLP conference]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://alp.oktem.me/img/emnlp-header.png" /><media:content medium="image" url="https://alp.oktem.me/img/emnlp-header.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>